StarRocks on Kubernetes FMEA - Part 1 Prerequisites
By Harsh Mishra
This is a two-part series on performing FMEA to test production readiness of StarRocks on GKE.
Introduction
In May 2026, I assessed whether a customer could self-host StarRocks on Google Kubernetes Engine (GKE). I wanted to know which failures the deployment could tolerate and what recovering from them would take.
We used Failure Modes and Effects Analysis (FMEA) to identify how the deployment could fail, trace the effects, and decide what to test. This is Part 1 of the series that covers the deployment, its quorum requirements, and how we designed the assessment. In Part 2 we will see the tests in action and what we found.
Audience and Key Takeaways
This series is for SREs, Kubernetes administrators, and engineers evaluating a stateful system for production. You’ll learn what to understand about the system upfront, how to turn the guarantees your workload depends on into test cases, and how to scope the work to the time and resources you have. The series uses StarRocks, an open-source analytical data warehouse, as a case study and walks through the FMEA basics in enough depth to apply them to other stateful systems.
What Is FMEA and Why Use It?
Failure Modes and Effects Analysis (FMEA) is a structured way to identify how a system can fail, understand the consequences, and decide how to prevent, detect, or recover from those failures. For a distributed database, it helps us examine our assumptions about availability and recovery before a production outage puts them to the test.
We often evaluate databases with stress tests and benchmarks such as YCSB or TPC-C. These tell us how the system performs under load. Operational resilience raises a different set of questions. What happens if the leader disappears during a write? Can a restarted member rejoin? What does the client see when a partition leaves the cluster without quorum?
FMEA helps us decide which failures to test. It must not be confused with, Chaos engineering, which, uses controlled experiments on a running system to see how it responds to those failures.
Testing every possible failure is rarely practical. I started with the guarantees our deployment depended on, then picked scenarios that could challenge each one. We ran those experiments directly because the scope was small. For a larger assessment, a framework like Jepsen can automate parts of the work.
FMEA Terminology
Before describing the tests, let’s define five terms:
| Term | Meaning |
|---|---|
| Fault | A cause of an incorrect system state, such as a software defect, hardware malfunction, or misconfiguration. |
| Error | An incorrect internal state that can lead to a failure. |
| Failure | An event in which a component or system stops providing its required service. |
| Failure mode | The specific way it fails, for example, rejecting writes, returning incorrect results, or failing to start. |
| Failure effect | The consequence of that failure for other components, users, or the wider system. |
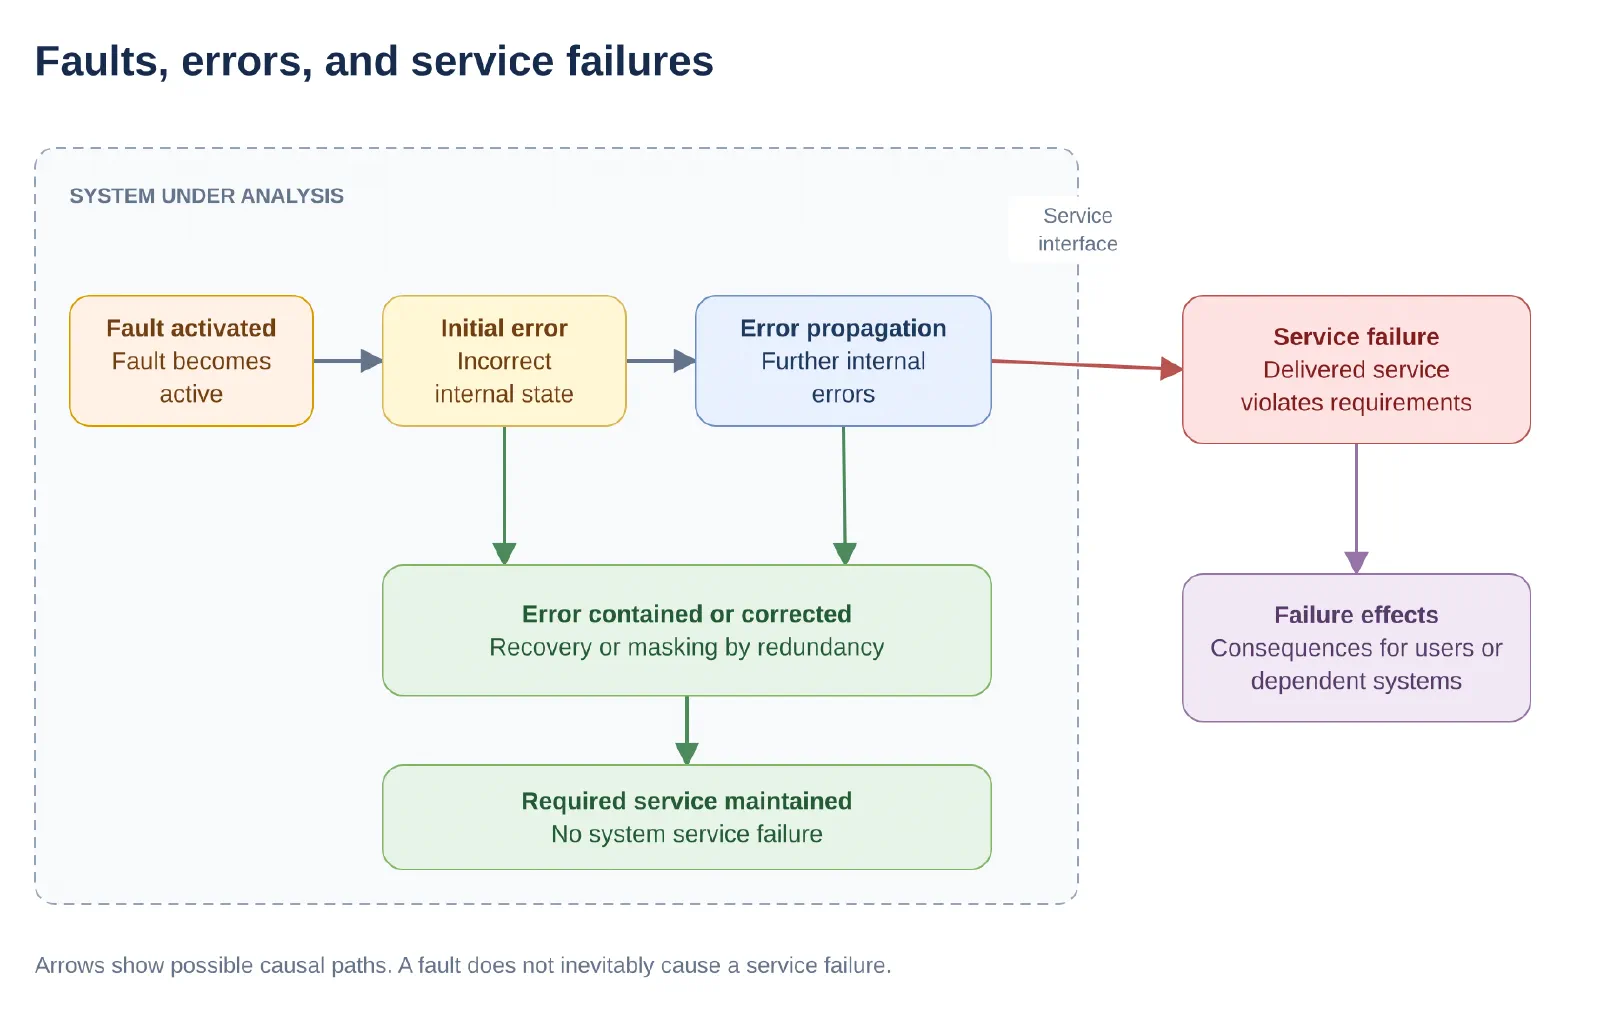
A fault can produce an error. If that error affects the service delivered, a failure occurs. Faults do not inevitably cause failures: redundancy or error handling may contain them. Dependability terminology
Example: insufficient braking in a bike
Suppose a motorcycle’s brake linings are worn beyond their service limit. When the rider brakes to avoid another vehicle, the motorcycle cannot slow sufficiently and collides.
- Fault: Excessively worn brake linings.
- Failure mode: Insufficient braking force when the brakes are applied.
- Failure: The braking system cannot deliver the required deceleration.
- Effects: A collision, potentially causing injury, death, or vehicle damage.
The failure mode describes how the braking system fails; the effects describe what happens as a result. FMEA traces these consequences through the wider system. NASA FMEA guidance
Why Use FMEA for Databases on Kubernetes?
FMEA helps identify how a database deployment can fail, how those failures affect users, and what the team needs to prevent or recover from them. It provides a structured way to examine questions such as:
- What can fail, and what is the impact?
What happens during pod eviction, node loss, network partitions, storage failures, or credential rotation? Which failures degrade service, interrupt writes, or require manual intervention? - Under what conditions do the expected guarantees hold?
Which replication settings, quorum requirements, placement rules, and shutdown procedures are necessary to preserve availability and data correctness? - Can the system recover?
Can failed members restart and rejoin automatically? When is operator intervention required? Which scenarios require backups, and have the relevant restore procedures been tested? - What operational work does the deployment require?
Which backup schedules, maintenance tasks, alerts, and runbooks must the team maintain? How should upgrades and configuration changes be performed? - What must applications handle?
How should clients respond to timeouts, connection loss, temporary unavailability, or writes whose outcome is unknown? Which assumptions need explicit tests? - Which fault injection experiments should we run?
FMEA helps prioritize scenarios, define expected behavior, and establish recovery criteria for controlled experiments.
The resulting analysis gives developers and on-call engineers a concrete record of failure risks, required controls, tested behavior, and unresolved assumptions.
Distributed System Models and Quorum
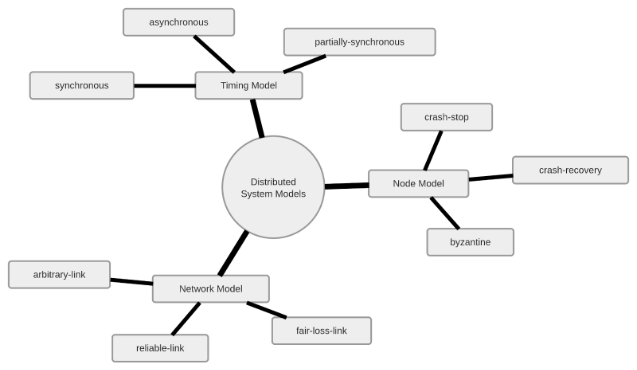
System models define the assumptions we make about process failures, communication, and timing. For a database deployment, these assumptions help explain how many unavailable members it can tolerate, what happens during a partition, and what recovery requires.
Node / Process Models
These models describe how a process can fail. In Kubernetes, the database process runs inside a container within a pod; restarting that container does not necessarily restore the database member to a usable state.
| Model | Behaviour |
|---|---|
| Crash-stop | A process stops executing and never resumes. The remaining members must operate without it. |
| Crash-recovery | A process can stop and later restart. Its memory state is lost, while persisted state may survive. |
| Byzantine | A process can behave arbitrarily, including sending incorrect or contradictory messages to other members. |
These are assumptions about process behaviour, not Kubernetes workload types. Distributed systems lecture notes
CrashLoopBackOff indicates repeated container failures with delays between restart attempts. It does not represent crash-stop behaviour or guarantee that the database has failed safely. Kubernetes pod lifecycle
An FE that knowingly reports a metadata write as committed without obtaining a voting majority is an example of Byzantine behaviour. During a network partition, an isolated FE may still believe it is the leader because it cannot reach its peers. The partition test checks whether quorum safety holds under that loss of communication.
Network and Timing Models
A network model describes what the system can assume about message delivery. In our frontend (FE) partition scenario, the isolated node cannot exchange messages with its voting peers, and a client timeout leaves the outcome of a write unknown. Distributed systems lecture notes
A timing model describes what the system can assume about how long processing and communication take. A slow response can look like a failed or unreachable process, so we check whether the majority can elect or retain a leader during the partition and whether the isolated FE catches up after communication returns. Dwork, Lynch, and Stockmeyer
Consensus, Quorum, and Reconciliation
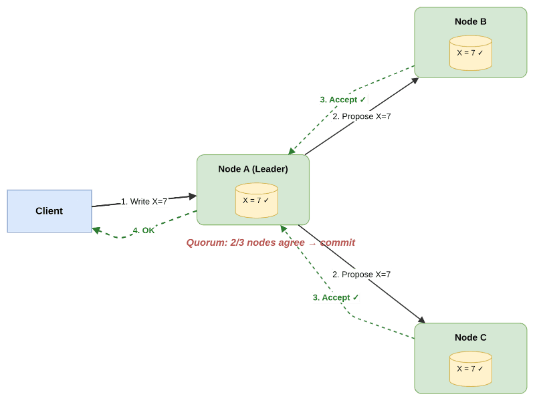
Suppose three nodes, A, B, and C, each store a copy of a value X. A client asks to change it from 10 to 7. Three concepts describe how the cluster handles the write and how a member catches up after a disruption.
- Consensus is how the nodes agree on which update to commit. In the diagram, A leads the protocol and proposes
X = 7. - Quorum is the set of participants the protocol requires to complete an operation. Here, two of the three voting nodes are enough to form a majority.
- Reconciliation brings actual state into line with the committed or desired state. If A and B commit
X = 7while C is unavailable, C still hasX = 10. When C returns, it catches up toX = 7.
Understanding Majority Quorum
Different distributed systems use different quorum rules. For simplicity, we’ll focus on majority quorum, commonly used in leader-based consensus protocols.
For a system with N voting members, a majority quorum requires:
Q = ⌊N / 2⌋ + 1
Here, N is the total number of voting members and Q is the minimum number needed for a majority.
Consider three nodes: A, B, and C.
Since there are three voting members, the majority is two.
If A is the leader and proposes a change, it needs acknowledgment from at least one other voting member to satisfy a majority-based replication requirement.
Now consider a few situations:
- C becomes unavailable: A and B can still form a majority.
- A becomes isolated: A cannot form a majority on its own. Depending on the consensus protocol, B and C may elect a new leader and continue operating.
- Both B and C become unavailable: A is the only remaining node and cannot form a majority.
This is why a three-node voting group can tolerate one unavailable member while retaining a majority.
The following table shows how this works for different cluster sizes.
| Voting members | Majority required | Unavailable members tolerated |
|---|---|---|
| 2 | 2 | 0 |
| 3 | 2 | 1 |
| 4 | 3 | 1 |
| 5 | 3 | 2 |
Notice something interesting: a four-node cluster cannot tolerate more unavailable voting members than a three-node cluster.
Adding another voting member does not always improve fault tolerance.
For a majority-based system to tolerate f unavailable members, the total number of voting members must satisfy:
N ≥ 2f + 1
For example, to tolerate two unavailable members, we need at least five voting members.
An important property of majority quorums is that any two majorities must overlap by at least one member.
Consensus protocols combine this property with additional rules for leader election, voting, and replication to preserve consistency.
Note: These examples assume crash failures and sufficient communication between surviving nodes. A majority alone does not guarantee correctness or availability under every type of failure.
Designing Our StarRocks Deployment
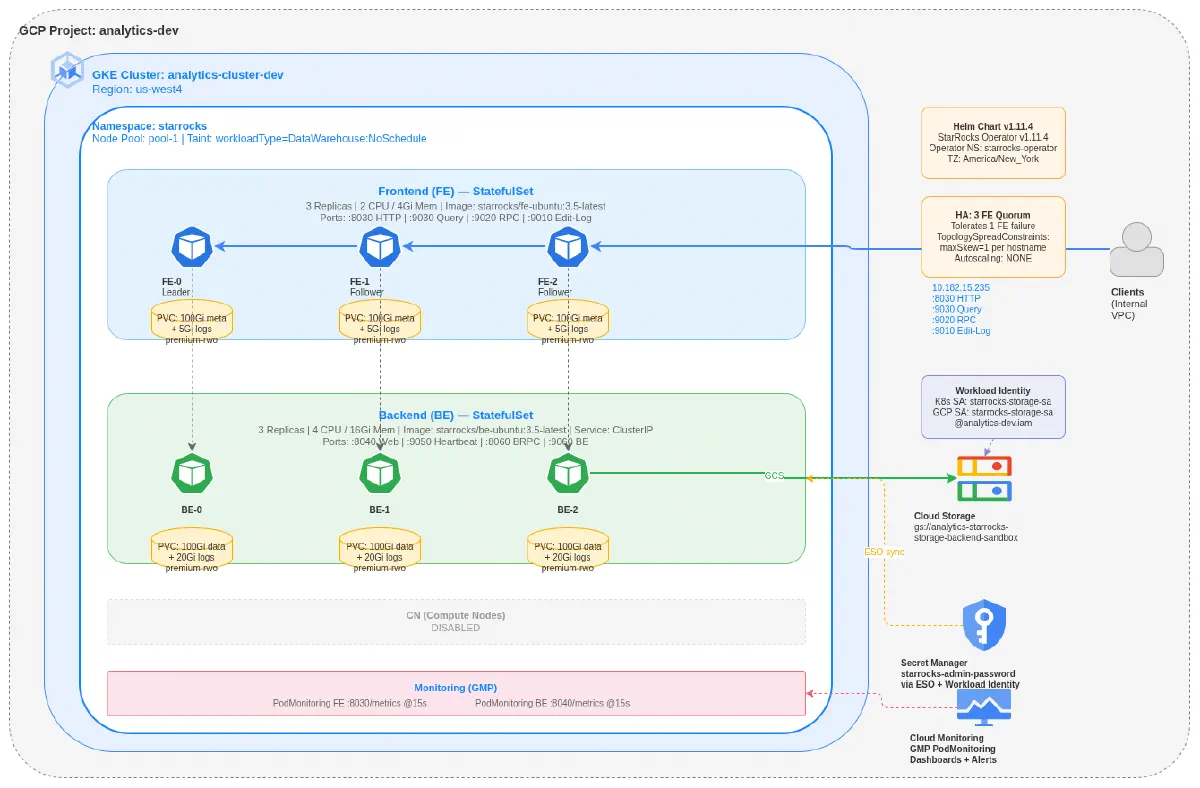
I deployed StarRocks 3.5 in shared-nothing mode on GKE using the StarRocks Kubernetes Operator, with three Frontend (FE) and three Backend (BE) nodes.
| Component | Configuration |
|---|---|
| Region | us-west4 |
| Frontends | 3 FEs (1 leader, 2 followers) |
| Backends | 3 BEs |
| Workloads | StatefulSets with persistent volumes |
| FE resources | 2 CPUs, 4 GiB RAM, 100 GiB metadata storage |
| BE resources | 4 CPUs, 16 GiB RAM, 100 GiB data storage |
| Storage class | premium-rwo with zonal persistent disks |
| Placement | FE and BE replicas spread by kubernetes.io/hostname, with one GKE worker per zone in the test pool |
| Replication | 3 replicas, majority write quorum |
Zone separation in this test came from the one-worker-per-zone layout. A topology spread constraint can use topology.kubernetes.io/zone to count replicas by zone. An FE and a BE can share a worker, so losing that worker can take out one member of each group. Kubernetes topology spread constraints
A pod can reuse its zonal disk only on a worker in the disk’s zone. If a drain or worker failure leaves no eligible worker in that zone, the replacement pod can stay Pending even when other zones have capacity. GKE persistent volumes
StarRocks separates responsibilities between two components:
- Frontends (FEs): Manage metadata, client connections, and query planning.
- Backends (BEs): Store data and execute queries.
Both components use replication, but their quorum requirements serve different purposes.
Reference: StarRocks Architecture
Frontends: Consensus for Metadata
FEs maintain database metadata, including information about tables, partitions, and schemas. StarRocks uses Berkeley DB Java Edition (BDB JE) for metadata replication and leader election.
There are three FE roles:
| Role | Responsibility |
|---|---|
| Leader | Coordinates metadata changes |
| Follower | Replicates metadata and participates in elections |
| Observer | Replicates metadata without voting |
Our deployment had three voting FEs (including the leader), requiring a majority of two.
N = 3, Q = 2
This means:
- One FE fails: The remaining two can maintain a majority and continue quorum-dependent operations. If the leader fails, they can elect a new one.
- Two FEs fail: The remaining node cannot form a majority, preventing new metadata commits that require quorum.
Observer FEs do not count toward the voting majority.
Reference: StarRocks Metadata Recovery
Backends: Quorum for Tablet Writes
Unlike FE metadata replication, Backend write quorum operates at the tablet level.
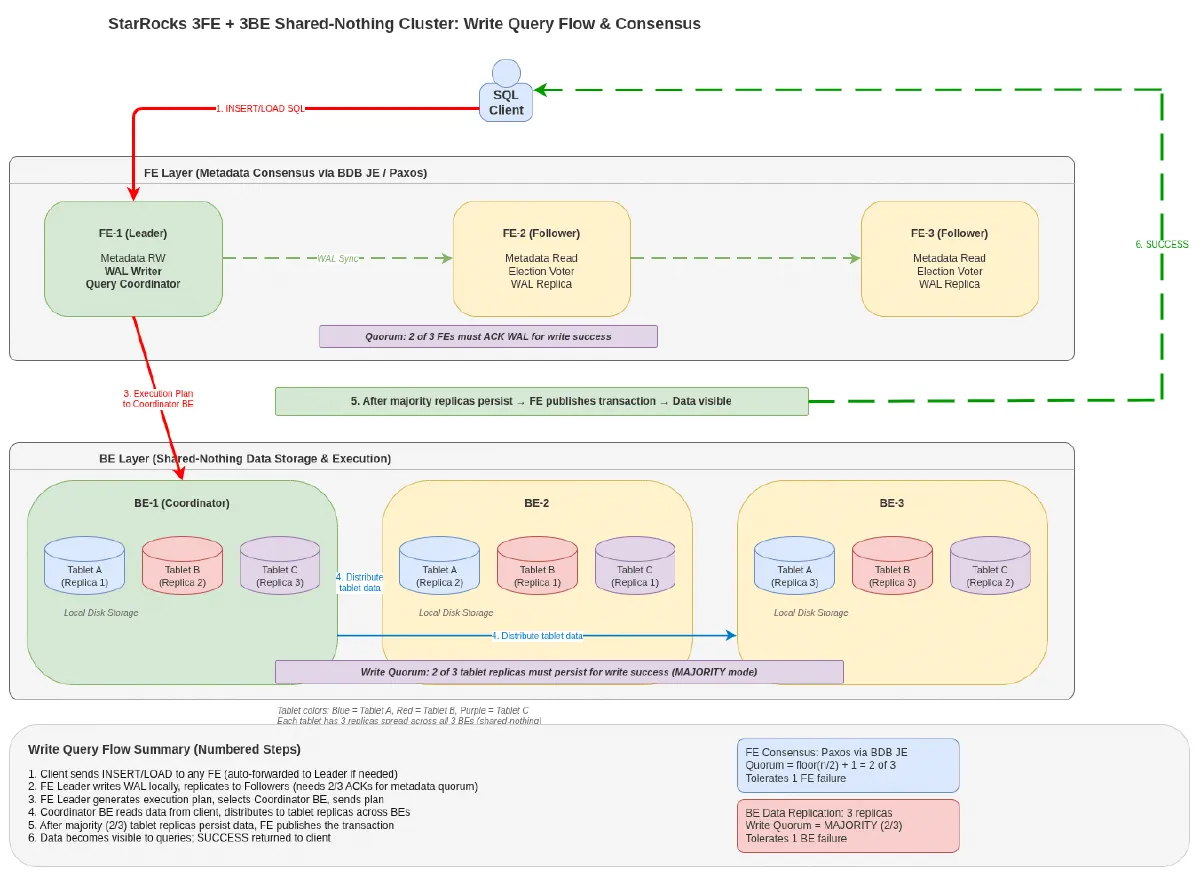
What is a Tablet?
A tablet is the basic unit of data storage, distribution, and replication in StarRocks.
Instead of storing an entire table on one machine, StarRocks divides its data into smaller units called tablets, organized through partitions and buckets.
Each tablet can have multiple replicas stored on different Backend nodes.
For example, with three BEs and replication_num = 3:
| Tablet | BE-A | BE-B | BE-C |
|---|---|---|---|
| Tablet 1 | Replica | Replica | Replica |
| Tablet 2 | Replica | Replica | Replica |
| Tablet 3 | Replica | Replica | Replica |
This allows StarRocks to distribute query processing and maintain redundant copies of data.
Tablet Replication and Write Quorum
Two table properties determine replication and write acknowledgment requirements:
replication_num: Number of replicas maintained per tablet.write_quorum: Number of replicas required to acknowledge a write.
StarRocks supports three write quorum policies:
| Policy | Required acknowledgments (3 replicas) |
|---|---|
ONE | 1 |
MAJORITY | 2 |
ALL | 3 |
Our tables used:
"replication_num" = "3",
"write_quorum" = "MAJORITY"
Therefore, at least two replicas of each affected tablet must acknowledge a write.
If one BE fails, the remaining two replicas can still satisfy the majority write quorum. If two replicas of a tablet become unavailable, writes to that tablet cannot meet the configured quorum.
Reference: StarRocks Replica Management
Zooming Out
Our StarRocks deployment had two independent quorum requirements:
| FE metadata quorum | BE write quorum | |
|---|---|---|
| Purpose | Metadata consistency and leader election | Replicated tablet writes |
| Participants | Voting FE nodes | Tablet replicas |
| Required majority | 2 of 3 FEs | 2 of 3 replicas |
| Failure tolerance | 1 voting FE | 1 replica per tablet |
A healthy FE majority cannot compensate for missing tablet replicas, and healthy tablet replicas cannot replace the FE majority required for metadata operations.
When failed nodes return, replication and recovery mechanisms help bring their state up to date.
This connects back to our three concepts: Consensus establishes agreement, quorum defines the required participation, and reconciliation restores the expected state.
Designing the FMEA
I started with the guarantees I expected from our StarRocks deployment on GKE. For each guarantee, I picked a failure that could put it under pressure and decided what evidence would count as a pass. That gave me three things to check in each scenario:
- Safety. Can an isolated FE commit a metadata change without a voting majority? Can a load be reported as successful when an affected tablet has too few replica acknowledgments?
- Availability. Which operations can clients still perform while the fault is active? Can they submit new loads, or do they see errors and timeouts during the disruption?
- Recovery. Can the affected member restart, rejoin, and restore the intended redundancy? If recovery requires an operator, what intervention is needed?
I assessed the FE metadata quorum and the BE tablet write quorum separately. In our deployment, each had a threshold of two out of three, but they counted different things. The FE check concerned voting members that could communicate and participate in metadata consensus. The BE check concerned successful write acknowledgments from replicas of each affected tablet. A load succeeding while one BE was unavailable could demonstrate continued write availability. Recovery required a separate check that the BE rejoined and its replicas became healthy again.
I grouped the scenarios by what could go wrong, what I expected to observe, and which failure assumptions each test used.
We ran the experiment with StarRocks Operator v1.11.1, which managed the FE and BE StatefulSets through the StarRocksCluster custom resource. That version provided no way to configure PodDisruptionBudgets (PDBs) through the custom resource. For the planned-drain scenario, we checked whether the remaining FEs could maintain a voting majority and whether writes could still reach quorum for each affected tablet. StarRocksCluster resource definition in v1.11.1
In the password rotation scenario, the BE startup script uses a MySQL client to connect to the FE as the StarRocks root user and register the backend. In our deployment, we had to inject the current root password separately into the BE container as MYSQL_PWD, sourced from a Kubernetes Secret. Changing the password in StarRocks does not update that environment variable. A running BE may keep serving while a replacement with a missing or stale value fails to authenticate and register. StarRocks Operator password rotation guide
| Scenario | What could go wrong | What I would check | Assumed failure model |
|---|---|---|---|
| FE follower or leader pod disappears | The FE group loses a member, and losing the leader can interrupt metadata operations. | Check whether the remaining voters retain a majority, whether they elect a new leader when needed, and whether the replacement FE rejoins. | Node: crash-recovery |
| A GKE worker is drained or abruptly replaced | A member may fail to recover after its pod is replaced, even when its persistent volume survives. | Treat planned drain and abrupt loss as separate cases. Check whether the replacement can schedule in the disk’s zone, start with usable state, and rejoin the cluster. | Node: crash-stop (abrupt worker loss) Node: crash-recovery (database member) |
An FE is isolated from its voting peers (Network Partition) | An isolated leader could keep acting on stale leadership information, or clients could continue sending requests to an unreachable member. | Check that the majority can elect or retain a leader. Verify that the isolated FE can neither commit a new metadata write nor report it as committed without a voting majority. Check that the isolated FE rejoins after connectivity returns. | Node: Byzantine Behaviour (minority FE starts accepting writes) Network: partition (link omission) |
| A BE becomes unavailable | An affected tablet may have too few healthy replicas to satisfy its write quorum. | Check whether loads can succeed with the remaining replicas and whether the cluster restores the intended replica count after recovery. | Node: crash-recovery |
| BEs restart after a root password rotation | Running BEs may keep serving while a replacement fails to register because its MYSQL_PWD is missing or stale. | Restart one BE first and check whether it can authenticate and register with the FE. Check whether tablet writes can still meet quorum if more BEs restart before the first recovers. | Node: crash-recovery |
For each scenario, I wanted evidence at three levels: what the client saw, what StarRocks reported about leadership and replica health, and what Kubernetes reported about pod lifecycle. A replacement pod could be running while its database member was still unable to register or serve traffic. A rejected load could also be the expected safety outcome when the required quorum was unavailable.
I started with one disruption at a time so I could trace its effects. Then I paired changes that can occur together during routine operations, such as rotating credentials and later replacing a pod. That distinction shaped the FMEA because a deployment can look healthy immediately after a change and still fail the next time a member has to start from scratch.
What’s Next
In Part 2, we will define the in-variants from the FMEA Design shown above. I will provide running Terraform Samples and demo you can try out on your own.